Just what do you need an RDBMS for, anyway?

If you are in the business of writing anything like an "enterprise application" (and these days, that's pretty much every programmer who's target platform doesn't come sealed in epoxy) then you store your data in an RDBMS.

And if you're at all up to speed with developments in the art of programming over the past thirty-odd years you write the application "logic", middle tier, call it what you will, in an object-oriented language (or, at least, something that looks quite a lot like one from a sufficient distance). And so you spend a deal of your time dealing with a thing called the "Object-Relational Impedance Mismatch".

There's money to be made from this. Oracle recently purchased what was originally a Smalltalk O-R mapping tool, Toplink. Like most of its ilk it allows programmers to maintain (by mostly manual processes) a huge pile of XML relating a bunch of tables in a database to a bunch of classes in a codebase. I focus on Toplink because that's where my experience with the topic largely lies, not through any great love or hatred of the product. Well, anyway, the aim of these tools is "transparent persistence", whereby modifications to the mapped objects make their way to the database automagically. (*) So, there's this arbitrary graph of objects that gets mapped onto this strict table-based model, via hierarchical text-based metadata. Ooo-kay.


"Translucent" Persistence

Except that the object graph isn't arbitrary. And the "transparency" is of a rather murky kind. "translucent persistence" might be a better term. At the time that you write the classes from the object graph will be instantiated the mapping tool will impose all sorts of constraints on what you can do, and how you do it. This is very far from the promise of orthogonal persistence. What happened to JSR 20, that's what I want to know.

For instance, if you want to get hold of an object that (you have to know) happens to be backed by the underlying database then what you do is obtain an entry point to the data, and search over it for the object you want. Unlike the navigation that you might expect to do in an object graph, instead you build...queries. Like this:
ExpressionBuilder builder = new ExpressionBuilder();
Expression expression =
builder.get("surname").equalsIgnoreCase("Smith");
Person p =
(Person) aSession.acquireUnitOfWork().readObject(
Person.class,
expression);
Yup, that's pretty transparent alright. Can't tell that there's anything other than plain old in-memory objects there. For Java fans: isn't it especially wonderful how the programmer had to mention the name of the class three times? So that it will be true, presumably.

Building these query objects can be a pain, though, if they get all complicated--which they do, always. I know one team that ended rolling its own library of query-building classes. Had a load of methods on them with names like "select" and "orderBy" and so forth...

Why do programmers put up with this? A lot of the time, habit. Which is to say, not thinking terribly hard about what it is they do that adds value.

To be fair, the modern RDBMS is a pretty amazing thing: high performance in time and space, robust, reliable, available...it's just that a lot of application programmers are a bit confused, I believe, about where the benefit of using an RDBMS lies.


If only an RDBMS were Realational

While it's true that what we have today in the widely used RDBMSs is a pale reflection of what the relational model is capable of, they are nevertheless closely related. So let's take a look at the ur-text of relational theory, Codd's paper of 1970 (back when "data base" was still two words). What's of interest about it is that it doesn't talk about persistence much at all. There is mention in passing that the data is "stored" in the "data bank" but the focus throughout is on the structure of the data, how that structure can be preserved in the face of updates to data and to what we would now call the schema, and how users of the data can be isolated from the details of how the data is held and changed.

Flowing from this are two principle advantages of using an RDBMS to store data:
  • ease of framing ad-hoc queries for decision support
  • robustness in the face of concurrent updates from multiple sources
That the data put into the database yesterday is still there today (even though the server was powered off overnight) is secondary. Immensely useful, but secondary. If we adopt a stance whereby we focus on the A, C, and I in ACID, and soft-pedal the D, some more interesting thinking becomes possible.


What if the data "never" changed?

If you are indeed in the business of business of writing anything like an enterprise app (and if you aren't, how come you read this far?), ask yourself this: how much of the code data source layer (or whatever you call it) of your stack could go away if the data it supplies to layers above it never changed? By "never", of course I mean "not during the lifetime of an application instance".

Now, the RDBMS crowd already distinguish between OLTP and OLAP, (and a very interesting debate that is, too--no really, it is) and the endpoint of moving in the OLAP direction is the data warehouse. And lot of regular RDBMS practice, predating the warehouse, allows for a highly optimised "read-only" route into the data involving a bunch of denormalized views and such. It's a failure mode to "denormalize for performance" even before the schema is built, never mind used for long enough to identify the frequent access patterns that will benefit from that denormalization, but when some user is going to need the same report updated time and again: go for it.


Data "corner shop"

Data warehouses are generally expected to be 1) gigantic, 2) concerned with transactional data that accumulates at a high rate (leading to 1) and 3) aimed at sophisticated reporting (the "analytical" bit of OLAP). The smaller volume, more task specific version is the ''data mart''.

Lets say that we are building a system where the data needed to satisfy the wants of an end-user changed over periods much longer that the duration of a user's typical interaction with the system. Why, then, would we worry about all that aSession.acquireUnitOfWork().readObject( blah blah blah stuff? We would have no need to do that for each user session. If the data changed slowly enough, there's be no need to do it for each instantiation of the (web) application itself. We can imagine the "transactions" getting consolidated in the warehouse (and condensed in the mart) might be things like "add a new item to the catalogue", or "change the price of this item". Happens on the timescale of days--or weeks. And furthermore, these changes might be known about, and actioned, some time in advance of being turned on for a particular application. But we have this idea avilable that access to the data that involves rapidly changing entities doens't have to go by the same route, or be maintained in the same way as that which changes slowly.

Phew! So, rolling all that together you can start to think about doing what the team who re-implemented SQL in Java whom I mentioned earlier did. Or, rather, what one of the more capable programmers did in his spare time because he was fed up with all that junk. Every now and again (say, once every 24 hours) run a bunch of queries (that's your data mart) over the data and pull out all the currently useful bits and write them to a file in one simple encoding or another. Then, when the application gets bounced, it reads that data and builds its in-memory object graph and uses that to serve user requests. Call out to the DB for really volatile stuff, but how much of that do you really, really have? Really?

Do this and I'll bet you find, as that team did when the databaseless version of their app was deployed, that it goes faster and scales better. Oh, and by isolating the application (in their case, completely) from a database they were able to very easily pull out a chunk of functionality to sell as a stand-alone application and/or plugin to other systems and enabled a whole new product line for their business. Nice.

This sort of decision should be the work of architects, but too often wouldn't even come up for disucssion as an option. Why is that?

(*) No approbation of the rather sinister ESR or his dubious schemes should be construed from this reference to the Jargon File

Keywords, Magic and (E)DSLs

Imagine you could write programs with text like this:
aJanitor open: aDoor with: aKey.
Pretty sweet. How might the implementation of open:with: look? Like this:
self insert: aKey into: aDoor; turn: aKey; push: aDoor.
Imagine how productive you could be if you could write code this way. Imagine how easy it would be to maintain code written this way. It's so clear what this code achieves (though maybe not quite how it works) that I'm not even going to explain it. This is Smalltalk.

A big part of the reason why Smalltalk is so great is this keyword message syntax (blocks help a lot, too, as we shall see). It allows code like the above, which look very much like natural language. If you are more familiar with curly bracket languages or similar, it can take a little effort to get used to reading code like this, but it's worth it.


No Magic

There's more to it than just ease or reading and writing, though. Smalltalk has no magic. Well actually, it has a lot of magic, but it enables all programmers to be magicians, whereas certain other languages hide their magic away. The language implementers grant themselves wizardly status, but deny it to the language user.

One kind of magic is a little bit of laziness around choosing alternatives. In Java we choose between two alternatives like this:
if(condition){
this.doOneThing();
} else {
this.doAnotherThing();
}
and we can be confident that one thing or the other will happen, but not both. That's actually quite clever, although the order that Java is usually taught in hides this. Imagine that if were a method on some object...ah yes, turns out that Java isn't really object oriented after all. Java has objects that instantiate classes that declare methods, it's true, but the code inside those methods, with if and switch and the rest, isn't object-oriented. Such a shame, as we shall see.

Anyway, imagine that Java were an OO language and that if, therefore, were a method. There would be a potential problem (assuming the near universal eager evaluation of function arguments). Our imagined ObjectJava code might look like this:
if(condition, {doOneThing();}, {doAnotherThing();});
which kind-of suggests that both the one thing and the other would get done. And this is the magic of the keyword if and it's funny syntax. What are those things with the {}'s? They're little lumps of code (possibly with local variables declared in them), and one of them gets run and one doesn't, under programmatic control. That's a pretty powerful feature, too powerful for the Java wizards to allow we working programmers to wield.

The syntax of our invented ObjectJava is pretty bad there, );}); isn't a thing of beauty, although it's not much worse than the way some real Java looks. The Smalltalk equivalent is much neater. Continuing with our janitorial example:
aDoor isAlarmed ifTrue: [self disarm: aDoor] ifFalse: [self openNormally: aDoor].
The [], conspicuously unlike the {} of Java, creates a new object, a so-called block, which contains the code to run. And the interesting thing about this is that ifTrue:ifFalse: is just a method. It's a method of the class Boolean. And Boolean has two subclasses: True and False, each of which is a Singleton. The sole instance of True is called true, and similarly for False.

The implementation of ifTrue:ifFalse: in True is(+):
ifTrue: t ifFalse: f
^ t value
and in False it is
ifTrue: t ifFalse: f
^ f value
(Note: ^ is how Smalltalk spells "return" and value is a method on blocks that returns the value of the code inside the block).

This is pretty much exactly the implementation of Booleans used in the Lambda Calculus, and that fact reveals one aspect of the close relationship between OO and functional programming.


(Embedded) Domain Specific Languages

Perhaps most astonishing about the Smalltalk approach is that Boolean values and selecting different actions based upon them is not part of the language. These are facilities provided by methods of classes in the Smalltalk standard library! This library (the "standard image") turns out to contain a large number of overlapping Embedded Domain Specific Languages--one of which, provided by the classes Boolean, True and False is specific to the domain of two-valued logic. That's a very remarkable thing. Most remarkable is what it says about the business of writing programs in Smalltalk.
There is no mechanism available to the Smalltalk programmer to create programs other than the creation of EDSLs
Even the Smalltalk programmers who write Smalltalk itself don't have any other (*) mechanisms available to them. And that's the benefit of No Magic: anything the language implementers can do, you can do too. And you end up doing what they language implementers do, that is, implement (a) language(s). Our example,
self insert: aKey into: aDoor; turn: aKey; push: aDoor.
is nothing more (and emphatically nothing less) than a statement about janitors, doors and keys written in an EDSL that knows about...janitors, doors and keys.


Dot Dispatch language

What about those of is who are not fortunate enough to be able to use Smalltalk in our work. What can be done in the languages where regular programmers are second-class citizens?

The best example that I've seen of an EDSL in Java is the language used to describe expectations in jMock. This language supports a certain style of programming that many folks are finding valuable. jMock allows us to write programs to talk about how other programs will behave. Like this:
mock.expects(once()).method("m").with( or(stringContains("hello"),
stringContains("howdy")) );
again, I think this is clear enough without explanation. You would use code like this within a programmer test to ensure that the test failed if some other object collaborating with our mock doens't call into the mock in the expected way.
It's worth digging into the implementation of jMock, not only because it is delightful code, but also to see the amount of heavy lifting that has to go on behind the scenes to make it possible for Java programmers to write code of the clarity seen above.


Productivity?

Building DSLs is the bread and butter of Smalltalk (and Lisp) programming, but is a bit of a struggle in the Java (and similar) worlds. The big vendors are attempting to fix this through the use of mighty tools in the interests of supporting a new-but-old-but-new model of development, a rather fishy proposition at best.

This is symptomatic of one way in which the industry has decayed. The message of Smalltalk (and Lisp) is that the route to productivity is to use simple tools with few features and allow everyone interested to build upon them. The favoured route at the moment is to encode every good idea into an all-singing all-dancing "solution", take it or leave it.

Once, the computer itself was locked away, ministered to by a priestly class who mediated your desire to perform computation. Then the (personal) computer revolution began to start and we could all gain direct access to our computing power, and grow our own way of using it. But the something went wrong and a new priestly class--the tool builders in the corporate software vendors--arose to try and put the genie back in the bottle (to mix an increasingly muddled metaphor). They must not be permitted to succeed.

(+) Well, kinda. If it were, then it would be, but for practical reasons it isn't. But for our purposes, it's exactly as if it is. Don't worry about it.

(*) Well, they only have the one: they can hack the virtual machine itself. But then so can you

Agility, Architecture and Scale

Is "scale later" a fatal mistake? And further, a symptom of the indiscipline and sloppy software development that some folks hide behind claims of Agility, according to Aditya.

Well, Aditya is commenting upon this advice from 37signals:
In the beginning, make building a solid core product your priority instead of obsessing over scalability and server farms. Create a great app and then worry about what to do once it's wildly successful. Otherwise you may waste energy, time, and money fixating on something that never even happens. [emphasis in original]
That's sound Agile and/or Lean advice. Aditya counters with a reference to this piece by Werner Vogels, CTO of Amazon.com Clearly, Werner knows a thing or two about large systems. And clearly, any new functionality that his teams implement must be capable of handling the sort of load that Amazon's customer base generates, within Amazon's large scale, high performance, highavailability system. But Amazon have been in business for over a decade as I write this, and that's not the scenario that 37signals are talking about. They are talking about what to do when you're in the first year of your new web-based business and you need to get a product in front of paying customers right now, or else there isn't going to be any scalability problem ten years down the line. Or even two.

Pragmatic?

37signals is a Ruby (on Rails) house, so they're joined up with the PragmaticProgramming movement. In The Pragmatic Programmer Hunt and Thomas present some techniques that will lead to a system that will have some degree of scalability:
  • tip 13 Eliminate effects between unrelated things
  • tip 41 Always design for concurrency
  • tip 45 Estimate the order of your algorithms
  • tip 46 Test your estimates
These essentialy architectural practices have other drivers, and other benefits, but they will also introduce into your system the points of flexibility and cleavage planes through into which mechanisms for improving scalability maybe inserted. Inserted later.

Now, the pragmatists hardly look as if they are indisciplined and sloppy, if they are following those tips. But there are always those other guys. For instance, while many fine developers would agree that often optimization is your worst enemy, there'll always be someone to come along with a counter story of a time when the optimization really should have been done. Similarly, the Extreme Programming advice that You Aren't Gonna Need It, and Do the Simplest Thing that Could Possibly Work are countered with stories about times when folks think that using them would have failed. Furthermore, folks claim that these practices are used by bad programmers to justify, well, being indisciplined and sloppy (usually because XP doesn't explicitly metion whatever thechnique their most recent book was about). In my experience it requires a great deal of discipline on the part of the typical programmer to apply YAGNI and DtSTtCPW, so action oriented, operationally biased and generally in love with doing the next cool, clever thing are they.

In isolation, out of context, these practices can be damaging. But one remedy is Worst Thing First. Notice the examples that Ron gives:
In the PlanningGame, users assign priority to stories, among other reasons, because of risks they perceive. "System must be able to pay 60,000 people in two hours. High priority." Developers assign technical risk similarly. "System must be able to marshal up to 60,000 networked PCs simultaneously for 1 minute each. High risk." We sit together and build consensus on what is risky, what needs a SpikeSolution, what order to do things. Is there a better way to identify worst things than to get together and work on it?
Those are performance and scale requirements. Being addressed up front. Because the customer wants them, so you really are going to need them.

Abstract Scalability

But that's scale, not scalability. Werner Vogels defines scalability this way:
A service is said to be scalable if when we increase the resources in a system, it results in increased performance in a manner proportional to resources added
This is an abstract quality referring to a hypothetical situation. A terribly difficult thing to do engineering about. When might you need to feel confident about this scalability? Well, if you were running an web 1.0 startup and your business model relies on capturing a dominant slice of the global market for your particular genius product in very short order, you might. You might very well need to be seen (by your VCs) spending money on the big iron needed to handle the load that would have to come to earn the revenue that would show them any kind of return.

On the other hand, if you know that the first day of the rollout of your new product it's going to get banged on by all n tens of thousands of employees of Yoyodyne worldwide, then you'd better be sure that it will operate at that scale. And if you're Werner Vogels and you expect your historical growth in user base to continue at whatever rate it is, you have a definite idea of what extra capacity you'll have to accommodate and when. But abstract scalability? Nah.

The key to the message from 37signals, and from XP is this: how far do you think Google would have got if the first thing Larry and Sergey had done in 1996 was to think "you know, this could get huge, so first up we should design a filesystem to handle huge data volumes across many machines and then devise an algorithm for distributing certain classes of problems across huge clusters" instead of building the search engine itself?

Sustainable Pace Supported

At last, pointers to hard number studies in support of the XP practice of "Sustainable Pace".

Once again, other industries are far ahead of software development in the depth and maturity of their thinking about work. This pull quote sums up the article nicely:
A hundred years of industrial research has proven beyond question that exhausted workers create errors that blow schedules, destroy equipment, create cost overruns, erode product quality, and threaten the bottom line. They are a danger to their projects, their managers, their employers, each other, and themselves. Any way you look at it, Crunch Mode used as a long-term strategy is economically indefensible. Longer hours do not increase output except in the short term. Crunch does not make the product ship sooner--it makes the product ready later . Crunch does not make the product better--it makes the product worse
Now, there have been times when I, as a development manager, have pushed back against pressure from my management to suggest to my reports that they enter "crunch mode" for an extended period (oh, say, the lasquarterer of disappointingng year). Once, I put together a spreadsheet that, although I didn't know it at the time, embodiesomethingng similar to Chapman's model, as mentioned by Evan. The covering email that announced this spreadsheet explained that I intended it to be used for scenario modelling: think up some scheme for deploying overtime, plug it into the model, see what improvement (or, more likely, decline) in productivity would come about. Or better still goal seek to the improvement desired, see what the model had to say about the assumptions that would have to be true for that improvement to materialise, and then judge if those assumptions were reasonable.

Those of you reading this who have any substantial experience in the software industry will not be surprised to learn that I nearly lost my job as a result.

And Evan addresses this:
Managers decide to crunch because they want to be able to tell their bosses "I did everything I could." They crunch because they value the butts in the chairs more than the brains creating games. They crunch because they haven't really thought about the job being done or the people doing it. They crunch because they have learned only the importance of appearing to do their best to instead of really of doing their best. And they crunch because, back when they were programmers or artists or testers or assistant producers or associate producers, that was the way they were taught to get things done.
There is a circle of abuse here, (real abuse; lives relationships and families are damaged), that must be broken if the software industry is to flourish.

Functional Style and Multiple Returns

In his excellent "programming in the small" series, Ivan Moore suggests that demanding a single exit point for a function is an example of cargo cult programming. I wonder if favouring or disfavouring that idiom has any connection with how much exposure a programmer has had to functional programming. Ivan's example showing the multiple return style:
void foo(boolean condition) {
if(condition){
return 5;
}else{
return 6;
}
}
bears a great resemblence to the (much terser) equivalent in Scheme:
(define (foo boolean)
(if boolean 5 6))
Why is the Scheme version so short? Firstly, Scheme has no syntax to speak of so nothing much gets in the way of expressing the computational idea. And secondly, in the functional paradigm we program by writing expressions for the computer to evaluate, rather than a sequence of instructions for it to follow. A use of foo, would look like this:

(display (foo #t))


which would print out 5 since the name #t stands for the boolean constant true. display writes out the value of its arguments. The value of (foo #t) is the value of (if #t 5 6) and if evaluates to the value of its second argument if its first evaluates to true, and the value of its third argument otherwise. That's harder to explain that to show. Anyway, (if #t 5 6) evaluates to 5. Notice that there is no return statement anywhere. All Scheme code is built of expressions that evaluate to some value, so a return is implied wherever there is no further level of evaluation to proceed down to, in this case when evaluating the literal constant 5.

This kind of thinking about programs, as expressions that evaluate to the desired result, leads to a lot of interesting places, can be very valuable, and crops up all over the place. Most importantly, it is relatively easy to think about, which makes it easy to write correct code in thie style.

Structured vs. Functional?

Ivan suggests that the single exit point style is a cargo cult much like the goto-less style--and both belong to the so-called "structured programming" tradition. The father of that tradition is E. W. Dijkstra, who offered a method for thinking about the other kind of programming, the sequence-of-instructions form (as seen in C, C++, Java, C#, Pascal, Delphi, etc etc), which is excruciatingly hard. Its a sad irony that the imperative style of programming tends to be taught first when it is so much harder to get right.

It seems to me that to prefer the multiple exit point form is to tend towards the functional (that is, expression evaluating) style, and thus towards easy correctness. And this is largely because functional programs tend to go to the essence of the problem being solved.

It is possible to do the single return style in Scheme, since it is an impure language:
(define (foo boolean)
(let ((return 0))
(if boolean (set! return 5)
(set! return 6))
return))
Without explaining how all that works it's still fairly clear that a lot of mechanics has been introduced: some local storage, some extra expressions for updating that storage, explicitly returning the value. All of this has got nothing to do with the essential thing of choosing 5 or 6.

Why would a programmer place upon themsleves the burden of understanding and maintaining all that non-essential stuff? And yet so many do, by clinging to the imperative style (do this, and then do this, and then do this) of programming, which in fact requires all the further overhead of structured programming to be tractable.

Visibility and Control

Something I said recently that made the listener's ears prick up, re use of (distributed) standups to manage outsourced development:
I would expect a daily handover would do much to raise visibility to you of what the outsourcers are doing--and visibility is the first step to control

MDA => Agile!?

Came across this article regarding the MDA. It took me long enough to get my head around the idea that it's the Model Driven Architecture, rather than just any old architecture that's driven by models. Except that Haywood tells us in the piece that actually there are two MDAs depending on which tool chain you buy. The difference is that one set of vendors builds tools to support an elaborative workflow from the Computation Independent Model through to a Platform Specific Model and another a translational one. Eh? Translation vs elaboration was one of the big arguments back in the days when there was an active marketplace for OO methodologies. Seems as if the MDA is intended to be transformational. Or possibly elaborationalist, depending it seems on whom you ask.

Steve Cook has this[pdf] (amongst other things) to say about MDA. Now, Steve was partly responsible for the Syntropy method, which features three kinds of model: Essential, Specification and Implementation--reflecting the view that one single modelling vocabulary won't do for capturing knowledge about the world, specifying a software system to deal with it or figuring out how to build such a system. That's a little bit like the MDA's distinction between Computation Independent Models, Platform Independent Models and Platform Specific Models. Kinda. But it's not clear what these models are really supposed to be written in. UML? The MDA is an OMG offering, and UML is the OMG's modelling language.

Unfortunately, it's sometimes quite hard to know what a given UML model is supposed to mean (without, ironically enough, showing the corresponding code), and so it's hard to see how automated translation of UML models is going to go anywhere interesting. During the last run at this sort of thing, the CASE tool boom of around ten years ago, I had a job in a C++ shop where all code was round-tripped through a leading tool. It wasn't unusual to have to go through certain hoops to get this tool to generate code that compiled at all, never mind do what I wanted it to do. Maybe the tools are a lot better now, although "OTI" Dave Thomas's fairly recent assessment of the MDA space makes me think not.

Meanwhile, Haywood makes this rather provocative statement:
Adopting MDA also requires a move towards agile development practices. While like many I'm an advocate of agile processes, it's still foreign to many organizations. The need for agile development follows from the fact that MDA requires models to be treated as software, hence they are the "as-is" view. Those organizations that used UML only for blueprints or sketches (Fowler's analysis [4.]) will find that MDA does not permit the use of UML in that way.
I suspect that it would come as a surprise to many Agile practitioners that adopting the MDA would make an organisation more agile (and that this is because you can't use UMLAsSketch!) But let's examine the claim in a little more detail.

Certainly the idea of keeping your whole model and code stack in sync at all times seems like an Agile idea. I'd expect that to be more of a strain on those folks who in the past have taken to producing huge UML models that no-one ever looks at, and not so much the sketchers, so maybe that does drive you in the Agile direction.

Extremely Agile

I have to be careful here, because I'm not just an Agilist, but an Extreme Programmer, so even other Agilists sometimes think I have some very strange ideas about development. The principles of Agile development compiled by the authors of the Agile Manifesto don't seem to say anything that would stop you from using MDA, but they do suggest that, not only do you maintain your UML CIM in-sync with your code in the reverse direction (which is what I understand Haywood to be talking about--don't let the code run away from the model) but that you regenerate the whole system CIM->PIM->PSM->code->deploy frequently. The principles suggest:
Deliver working software frequently, from a couple of weeks to a couple of months, with a preference to the shorter timescale.
Well, yeah. Actually, my preference is for a much shorter timescale: weekly releases do not seem too frequent to me. And I want to be able to release on any given day. And I want all my changes (to whatever artifact) reflected in a deployable system ASAP. By which I mean, within minutes. Beck recommends a Ten Minute Build, which in MDA terms would seem to mean running the whole workflow (modulo dependency analysis) all the way through and executing a suite of tests in ten minutes. Should make the hardware vendors happy.

Peer Review

Just recently I received an email from the organizers of a new conference concerned with the technique of peer review. This events seems to be largely concerned with the review process applied to scholarly papers but it got me thinking about "review by peers", something that I do a lot of.

As a practitioner of Extreme Programming of course I prefer to write production code as one member of a pair. And pair-programming is explicitly an activity needing an effort towards a peer relationship: the higher-powered programmer in the pair has to throttle back a little, and the lower-powered one stretch. Peer-review of papers usually involves a panel of reviewers for each submission, and if you rotate people through pairs often enough (which might turn out to be very often indeed if this experience report[pdf] is anything to go by) then it won't be long before the code changes you make have been thoroughly reviewed by the time it gets checked in.

Then again, during the planning game I like to use Delphi techniques to explore possibilities, reach consensus, and obtain estimates. Delphi works by having a group of, as they are called in the technique, "experts", who are by definition peers, iteratively review a proposal or (answer to a) question. Interestingly, the anonymous nature of the input to a Delphi review would seem to fix some of the problems that occur when using less formal means to reach a consensus.

In development shops that don't do pairing, but do care about quality all the same, you'll often come across code review techniques of one sort or another. Fagan Inspection seems to be the best way to get this done with small groups, although my experience it is ferociously expensive and although produces excellent results perhaps doesn't offer great value-for-money. YMMV. If you have a (potentially) large group available, then the Open Source route is also a good one. Can be very slow, but also very effective, and (like the National Health Service), free of cost at the point of delivery...

And then there's reviewing conference sessions and papers and journal papers and drafts of books. This can be pretty excruciating work. As a reviewer, I whish more authors would heed this advice when preparing their submissions. As an author, I whish more conferences worked along the lines of the PLoPs, which are all about very intensive, hands-on, in the room, right before your eyes peer review.

Although it is (in)famously possible for a clever and resourceful author to get carefully crafted utter tosh published in a supposedly serious journal, there have also been cases of what seems to be genuine fraud (as it were) getting past the review process in vary hard science fields indeed. One has to wonder if this isn't, as with the remarkable ease with which dubious patents may be obtained these days, mostly due to reviewers being snowed under.

On the other hand, the organisers of that conference on peer review I mentioned up at the top are themselves notorious for accepting nonsense papers without review. In a spirit of enquiry I replied politely to the email suggesting that I probably wouldn't be able to attend the conference, but that I would be interested in helping out with the proposed book on peer review--as a reviewer. We'll see what comes of that.

Something Fishy

Just recently I've come across several uses in quick successon of would-be aphorisms to do with fish. It seems to be considered common knowledge that fish don't have a word for water, and that you couldn't ask a fish what water tastes like, and so forth. Well, you could argue, as this poem does, that it's perhaps likely that fish (supposing they have language) wouldn't have exactly one word for water. But on the face of it, the claims are nonsense. We have a word for air. And I can ask you what air smells like.

Generally, the folks using these sayings are making some point about people not being able to articulate thoughts, or even have thoughts, about their setting, about the context within which their lives are lead. Often with satirical intent. And ther's something to the idea that folks don't notice their surroundings much. But then maybe that depends on where you were educated, to some extent.

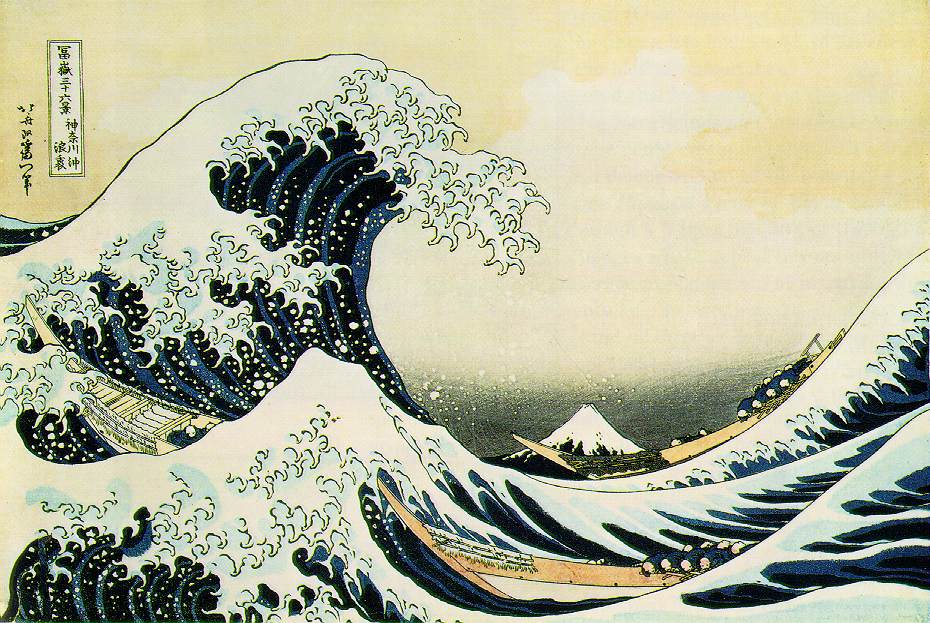
You've probably seen this picture, generally known in the West as The Great Wave. Folks writing about fractals and the scale-free geometry of natural shapes (something also found in other, perhaps surprising, places) often like to refer to The Great Wave and other prints by Hokusai, or to things that resemble it. But the subject (in the Western sense) of that print is not the wave. The Great Wave is one of a series called 36 Views of Mt Fuji. The funny thing is that in The Great Wave, as in quite a few of the other 46 [sic] prints, Fuji-san is hardly visible. It's there, but way off in the distance, a blip in the horizon.

What significance has this? Maybe a lot, if you hyave anyhting to do with collaborating across Eastern and Western cultures, and if this the conclusions in this book hold up.

A Naming Quandary in C#

Today I did some C# programming (my first, actually), and came across an interesting conundrum regarding the syntax of delegates.

Delegates are C#'s replacement for C++ pointers-to-(member)-functions. They are declared using a syntax a bit like a C-style function prototype. I tend to type curly bracket languages with a heavy C accent--I've been known to declare the argument of a Java main method as Object[] argv. So without thinking about it too much I typed my first ever delegate declaration something like this:
delegate void doStuff(object arg);
(all names have been changed to protect my employer's IP)

And then a new delegate object can be created, like this
doStuff sd = new doStuff(stuffDoer.doYourThing);
Where stuffDoer is an instance of a class with a method who's type signature (but not name) matches the type of the delegate. So there's a kind of duck typing for methods going on here.

Then, sd can be passed into a method declared like this:
public void doStuffUsing(stuffDoer doStuffWith){
doStuffWith(anObject)
}
in this way:
foo.doStuffUsing(sd);
Do you see my problem?

In the C/C++ world there is a desire to make the declaration and use of an identifier as similar as possible. That's why a pointer-to-member-function is declared (and initialized) like this:
void (StuffDoer::*fptr)(void*) = &StuffDoer::doYourThing;
and then used like this:
void SomeClass::doStuffUsing(void (StuffDoer::*fptr)(void*)){
StuffDoer sd;
(sd.*fptr)(this.pObject);
}
The C# syntax is clearer and more concise, by a long way, and the delegate has the nice (and safer) feature that it closes over the target object. In fact delegates have a property on them called Target that holds a reference to that object.

But the C++ form is more consistent, there's a direct 1:1 relationship between almost all the parts of the declaration, mention and use. The places where there isn't that relationship are marked by the dereference syntax.

Now, the syntax of the declaration of the delegate, delegate void doStuff(object arg) does look a lot like a use, like doStuffWith(anObject) which is cool. But what looks like a method name in the declaration is really the name of the type of delegate object. Thus mentions of the delegate type, such as
doStuff sd = new doStuff(stuffDoer.doYourThing)
look a bit fishy to me, for that reason.

So, I thought, maybe it should be delegate void DoStuff(object arg) so that creating the delegate looks like a constructor call:
DoStuff sd = new DoStuff(stuffDoer.doYourThing);
But these don't look right next to each other either, because the parameter to the constructor call is in no way related to what looks like corresponding parameter seen in the delegate declaration. Ouch.

Looking at the MSDN example (often highly dubious as that source can be), it looks to me as if there is anyway a convention in the C# world to name properties and methods with a leading capital anyway, which also looks very odd to me. Not to mention the type object being spelled with an "o" not an "O"

The Power of Protocols

There's this friend of mine who has an idea he likes to drop into conversations now and again about the significance of teh interweb having been invented by a physicist (or somebody like one), not a computer scientist (or somebody like one). A computer scientist, you see, would never have tolerated all those dangling pointers. But the possibility of dangling pointers is one of the things that makes the Web so easy to use, and from its ease of use comes its utility. No need to wonder if the implications of this have any significance for the continued utter irrelevance of Project Xanadu to the world. Ted Nelson has stated:
The Xanadu® project did not "fail to invent HTML". HTML is precisely what we were trying to PREVENT-- ever-breaking links, links going outward only, quotes you can't follow to their origins, no version management, no rights management.
(BTW, the complete absence of any semantically useful markup whatever on the source page for this quote is a miracle of irony)

Meanwhile a retrospective air has come across certain folks in the web world. Unusually for such a neophile bunch a certain amount of harking back (with suitably cynical commentary on the present day mixed in) has gone on. And so we are presented with what's being advertised as the first ever web page. One reddit contributor makes the observation that
it's also quite reassuring to see that the page still displays exactly as it was intended in 92. a few years later i was making sites with tables, and probably naively using ie-specific markup, which now look completely heinous. Another example of why adhering to standards increases the longevity of your data.
Indeed.

It seems as if info.cern.ch no longer resolves, but if it did then some of the original hyperlinks in that page would still work. That's amazing. Microsoft have also indulged in some digging around in the archives, and present their earliest homepage. Just an image, sadly, however, the wayback machine has got a very early corporate-stylee Microsoft home page with some links on it that (after the wayback munging is removed) do still work. They don't necessarily go where they say they go, although some of them do, and that's amazing squared.

Why am I amazed? Because I can't even begin to imagine going to the server end of most other distributed information systems (certainly none of the ones that I've built) and trying to use them in exactly the way that was intended ten or more years previously and expecting to get anything sensible back. Think about trying to connect to a remote object over an ORB with ten years between client and server. How does the Web mange to do the right thing?

In several ways: firstly, (as Berners-Lee points out, but I've lost the link) there is no reason that a URI should ever go stale, being neither the address of a location in space nor a pointer to an object. Secondly, and more importantly, the web works on an open text-based protocol. Ten year old and more email servers will provide a certain level of functionality by the same means. Thirdly, browsers are very lenient in how they interpret the HTML they receive, showing the user their best effort at rendering a page. That's a lot of sloppiness, a lot of flexibility, a lot of power.

All the rambling above is an excuse to link to this presentation (pdf) by Dick Gabriel, which covers this ground in more depth and with more eloquence, most especially the remarkable benefits that come from building a system out of components communicating via protocols rather than APIs.

Gabriel is a very interesting guy, and his other essays are well worth studying.

Hello

In the past I have said some rather harsh things about the blogosphere. And now here I am blogging. So what's changed? I stand by my earlier comments as an accurate description of my thoughts at the time. Since then, more and more people that I know and respect have begun blogging, and I have found more and more higher quality content in blogs generally. And have come to the conclusion that blogging has grown into something interesting and useful.

Also, I find that I'd like a place to punt ideas to a (potentially) wide audience that is both more under (my) control than, say, an egroup, but not requiring the discipline of my static web pages. This is it.